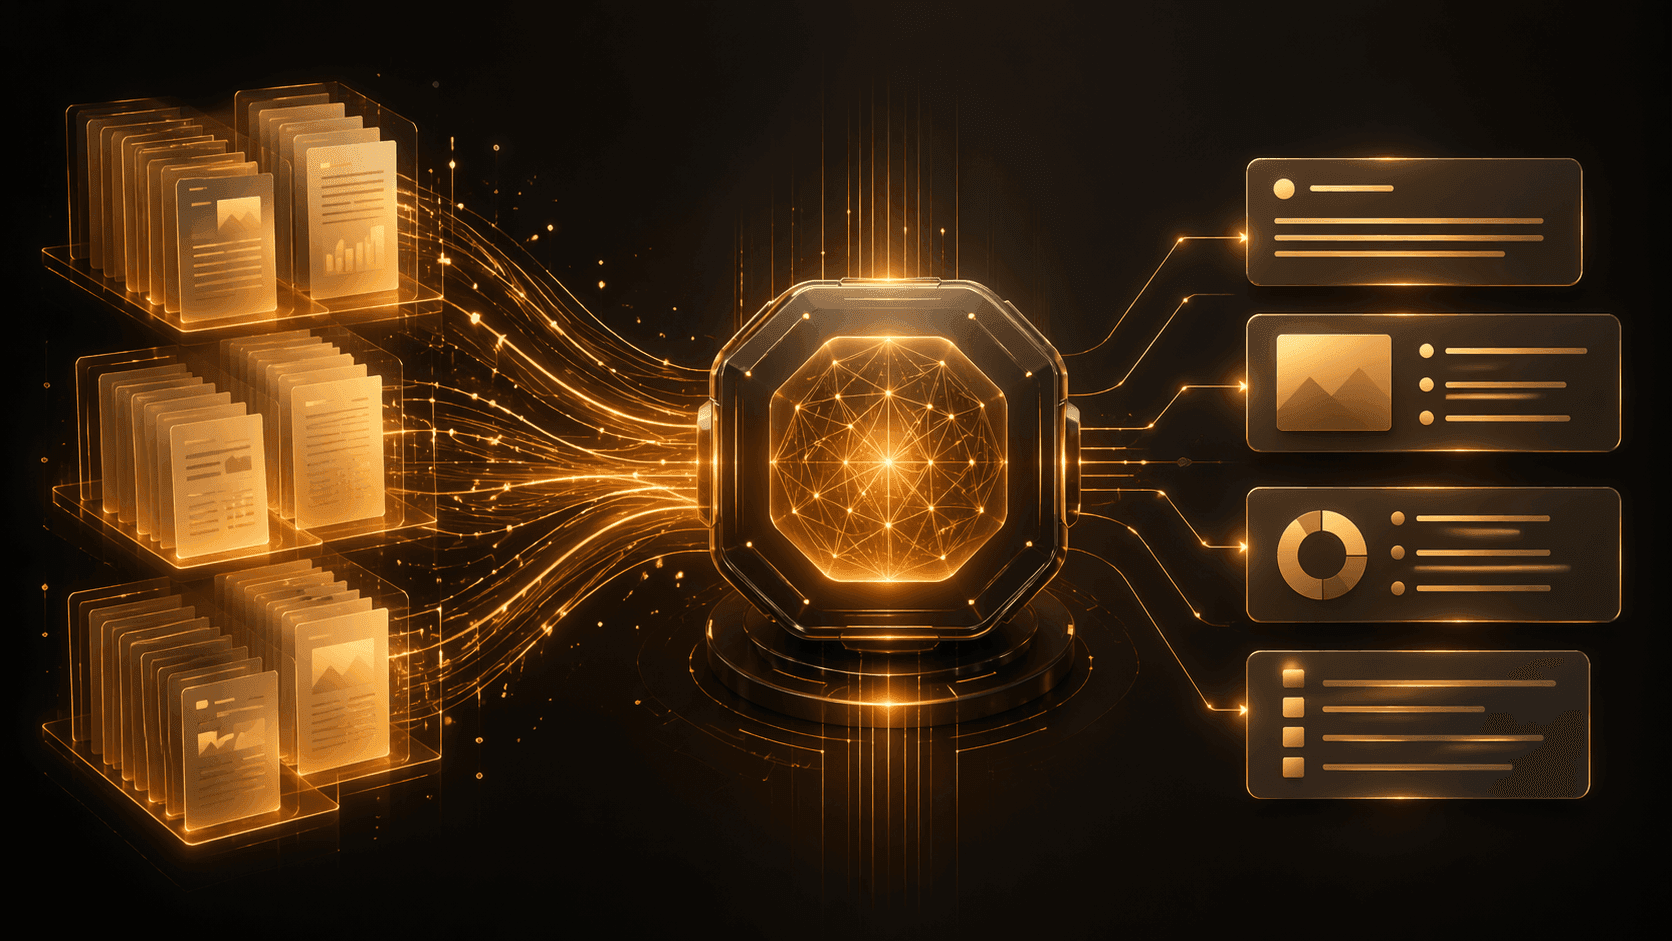
Large language models are powerful. But they have a fundamental limitation: they only know what they were trained on. Ask a model about your internal documentation, your latest product data, or your company's proprietary knowledge - and it will either confess ignorance or, worse, confidently hallucinate an answer.
Retrieval-Augmented Generation - RAG - solves this problem. It is the most widely adopted approach for making AI systems accurate, contextually grounded, and useful with real business data. Understanding how RAG works - and how to implement it well - is essential for any team building AI-powered products today.
What Is RAG?
Retrieval-Augmented Generation is an architecture that combines two components: a retrieval system that finds relevant information from a knowledge base, and a generation model (an LLM) that uses that retrieved information to produce accurate, grounded responses.
In plain terms: instead of asking the LLM to answer from memory, you first find the most relevant documents from your own data, inject them into the prompt as context, and then ask the LLM to answer based on that context.
The result is an AI system that can answer questions about your data accurately - without needing to be retrained, and without making things up.
Why RAG Matters: The Problem It Solves
Without RAG, LLM-powered applications face several critical limitations:
- Knowledge cutoff: LLMs are trained on data up to a certain date. They have no knowledge of anything that happened after that cutoff.
- No access to private data: By default, LLMs know nothing about your company's internal documents, products, customers, or processes.
- Hallucination: When asked about topics outside their training data, LLMs frequently generate plausible-sounding but incorrect information.
- Context window limits: You cannot simply paste your entire knowledge base into a prompt. RAG retrieves only the most relevant pieces and passes those.
RAG addresses all four. It connects the LLM to your data, keeps answers grounded in retrieved facts, and scales to large knowledge bases efficiently.
How RAG Works: The Technical Flow
A typical RAG pipeline involves four main stages:
1. Document Ingestion and Chunking
Your knowledge base - PDFs, Word documents, web pages, database records, product documentation - is processed and split into chunks. Chunk size matters: too small and context is lost; too large and retrieval precision suffers. Typical chunk sizes range from 200 to 1,000 tokens, often with overlap to preserve context across chunk boundaries.
2. Embedding and Vector Storage
Each chunk is converted into a high-dimensional vector representation using an embedding model (such as OpenAI's text-embedding-3-large, or open-source models like BGE or E5). These vectors are stored in a vector database - Pinecone, Weaviate, Qdrant, ChromaDB, or pgvector depending on your infrastructure preferences.
The embedding model transforms text into a numerical representation that captures semantic meaning. Chunks that are semantically similar have vectors that are mathematically close to each other - which is what makes semantic search possible.
3. Retrieval
When a user submits a query, the same embedding model converts it into a vector. The vector database is searched for the K chunks whose vectors are most similar to the query vector (typically using cosine similarity or dot product). These top-K chunks represent the most semantically relevant pieces of your knowledge base for this specific question.
4. Augmented Generation
The retrieved chunks are injected into the LLM's prompt as context, alongside the original user query. The LLM is instructed to answer the question using the provided context. The result is a response grounded in your actual data - accurate, specific, and verifiable against the source documents.
Advanced RAG Techniques
Basic RAG works well for many use cases, but production systems often need more sophisticated approaches:
- Hybrid Search: Combining dense vector search (semantic) with sparse keyword search (BM25) improves recall for queries where exact keyword matching matters alongside semantic similarity.
- Re-ranking: After initial retrieval, a cross-encoder model re-ranks the retrieved chunks by relevance to the query. This significantly improves precision, especially for complex queries.
- Query Rewriting: The original user query is rewritten or expanded by an LLM before retrieval - improving recall for vague, ambiguous, or multi-faceted questions.
- Multi-hop Retrieval: For questions that require synthesising information from multiple documents, the system performs multiple retrieval steps, each informed by what was retrieved in the previous step.
- Metadata Filtering: Chunks are tagged with metadata (source, date, category, author) that can be used to filter retrieval before semantic search - reducing noise and improving relevance.
When to Use RAG vs. Fine-Tuning
A common question is whether to use RAG or fine-tune a model on domain-specific data. The answer depends on what you are trying to achieve:
- Use RAG when you need the model to answer questions based on your current, frequently updated data. RAG is fast to update - add new documents, re-embed, done.
- Use fine-tuning when you want the model to adopt a specific style, format, or domain vocabulary - not just access new information. Fine-tuning teaches the model how to behave; RAG teaches it what to know.
- Use both for the highest-performing systems: fine-tune the model on domain terminology and tone, then use RAG to keep its knowledge current and accurate.
Real-World RAG Applications
RAG is not a theoretical concept - it is in production across a wide range of industries:
- Enterprise knowledge bases and internal Q&A systems
- Customer support chatbots grounded in product documentation
- Legal and compliance research tools
- Medical and clinical information retrieval systems
- Financial analysis and research platforms
- Sales enablement tools that surface relevant case studies and pricing data
The common thread: these are all applications where the cost of a hallucinated or outdated answer is high, and where the knowledge base is too large to fit in a prompt.
Building RAG Systems with Savyasachi Infotech
At Savyasachi Infotech, we design and implement RAG pipelines that connect AI models to your internal data, documents, and knowledge bases. We handle every layer - document ingestion, chunking strategy, embedding model selection, vector database setup, retrieval tuning, and prompt engineering - to build systems that are accurate, reliable, and fast.
We have implemented RAG in production for research platforms, document analysis tools, and enterprise Q&A systems, including systems that run entirely on locally deployed models for maximum data privacy. Talk to our team about building a RAG solution for your business.
Evaluating RAG System Quality
A RAG system is only as good as the quality of its retrieval and the quality of its generation. Evaluating a RAG system requires measuring both components. On the retrieval side, the key metric is recall - does the retrieval step consistently surface the most relevant chunks for a given query? On the generation side, the key metrics are faithfulness (does the answer accurately reflect the retrieved context?) and answer relevance (does the answer actually address the question asked?).
Frameworks like RAGAS and TruLens provide automated evaluation pipelines for RAG systems that measure these dimensions at scale. Running regular evaluations - especially when the knowledge base changes significantly or when the underlying model is updated - is essential to maintaining the quality of a production RAG system. The cost of a hallucinated or misleading answer in a business-critical AI application is often far higher than the cost of thorough evaluation.
Choosing the Right Embedding Model
The embedding model is one of the most important choices in a RAG system. It determines the quality of semantic search - and therefore the quality of retrieval. OpenAI's text-embedding-3-large and text-embedding-3-small offer strong performance with the convenience of an API. For on-premises or privacy-constrained deployments, open-source models like BGE-M3, E5-large, and GTE-Qwen deliver competitive performance without sending data to external services.
The right choice depends on your accuracy requirements, your data privacy constraints, and your cost and latency budget. In most cases, starting with a well-established API-based model and measuring retrieval quality on your specific data is the most efficient path to a strong initial system. Open-source alternatives can be evaluated later if cost or privacy becomes a constraint at scale.
Ready to Build a RAG System That Actually Works in Production?
The difference between a RAG prototype and a production RAG system is the difference between a demo and a product. Getting retrieval quality, latency, cost, and safety right in production requires more than assembling a pipeline - it requires careful design at every layer.
At Savyasachi Infotech, we build RAG systems for real business applications - enterprise knowledge bases, document analysis tools, customer support AI, and research platforms. We have deployed RAG on both cloud LLMs and locally hosted models for clients with strict data privacy requirements. We handle everything: document ingestion, embedding, vector store, retrieval tuning, and generation quality.
Book a free consultation. Describe your data and your use case, and we will design the right RAG architecture for your specific requirements.